
Last updated:
About Alerting
Dash0 provides two complementary approaches to alerting:
- Check rules — threshold-based alerting that fires immediately when conditions are met. Use them to detect performance degradations, error spikes, and service outages.
- SLOs (Service Level Objectives) — reliability targets measured against an error budget over a time window. Use them to track whether your service is as reliable as your users expect.
The Failed Checks View shows you which check rules are currently failing, helping you identify and respond to performance issues and outages affecting your infrastructure and services.
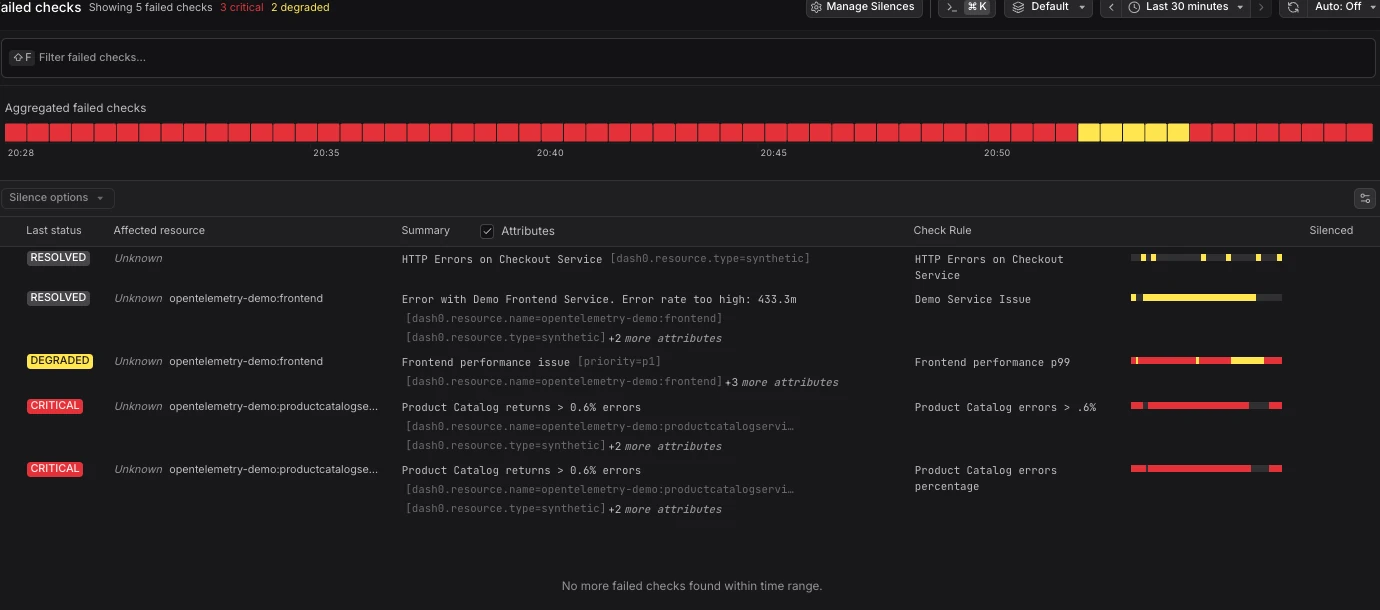
By setting up checks to monitor key metrics and thresholds, you can receive instant alerts, so that you can address issues before they affect customers or disrupt operations.
Monitor your systems by checking metrics, logs, and traces — including RED metrics derived from tracing telemetry and synthetic checks that continuously verify service availability.
With Dash0 Checks, you can:
- Streamline monitoring and response workflows
- Improve operational efficiency
- Maximize system performance
Access and Permissions
Creating check rules requires the Create Check Rule dataset permission. Admins and dataset Maintainers have it by default; other members can receive it through dataset permissions. A check rule can affect service health and send notifications to your team's on-call channels. Users without this permission cannot create check rules.
Creating SLOs works the same way: it needs the Create SLO dataset permission, which Admins and dataset Maintainers have by default. SLOs cannot be created in demo datasets.
Dashboards, by contrast, can be created by any user since they are purely visual and do not affect service health.
How Alerting Works
Alerting is a regular evaluation to determine whether certain conditions are met. Each failed check is associated with a service based on the attributes of the resulting time series — such as the resource identifier and service name. The coloring you see on service maps reflects the outcome of these checks:
- Gray — healthy, no active check failures
- Yellow — degraded threshold exceeded
- Red — critical threshold exceeded
All alerting is based on counting or measuring values and comparing them against defined numerical thresholds. From a single check rule, any number of distinct time series can fail simultaneously, each representing a separate check result.
Alerting Model
Dash0's alerting model extends the Prometheus alerting model. In Prometheus, an alert fires when the PromQL expression returns more than zero time series. Dash0 adds an optional $__threshold symbol that lets you specify degraded and critical severity thresholds — but every valid Prometheus alert rule is also a valid Dash0 check rule, with no modifications required.
Synthetic Checks
Synthetic checks are a form of alerting that continuously test service availability using HTTP requests (effectively curl plus alerting). They are kept separate from check rules in the UI, but work on the same underlying notification and routing infrastructure. When creating a synthetic check, you can assign notification channels in the same way as regular check rules.
Get Started
The fastest way to create check rules is to ask Agent0 — describe what you want to monitor and it will generate the check rule for you. For advanced use cases, you can write PromQL directly.
Dash0 is 100% PromQL compatible — existing alerts based on PromQL queries can be imported without modification using the CLI, Terraform provider, Kubernetes Operator, or Agent0.
Provide Context for Faster Response
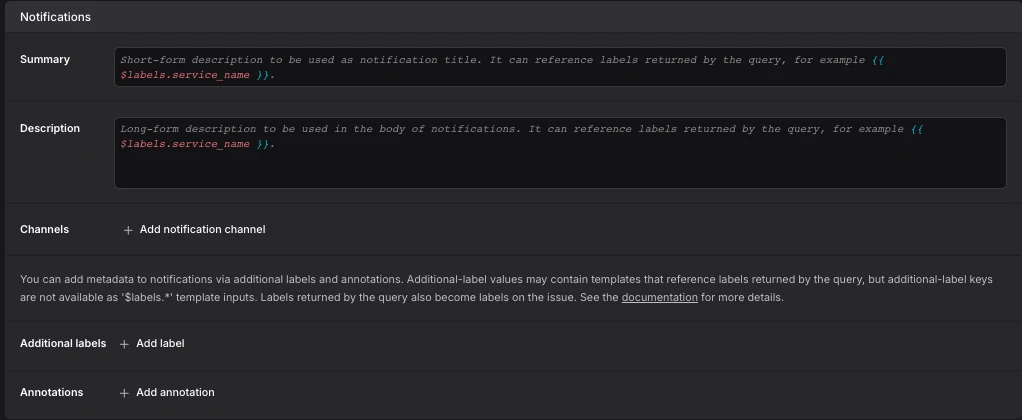
Use a check rule's Notifications card to explain the failure in its summary and description, choose notification channels, and attach labels for routing. Template variables let messages include values from the failed check, such as its service name and observed value.
SLOs: Reliability Targets with Error Budgets
Service Level Objectives (SLOs) build on the check rule engine with an error budget, shifting the question from "did this one request fail?" to "is the service as reliable as our users expect?"
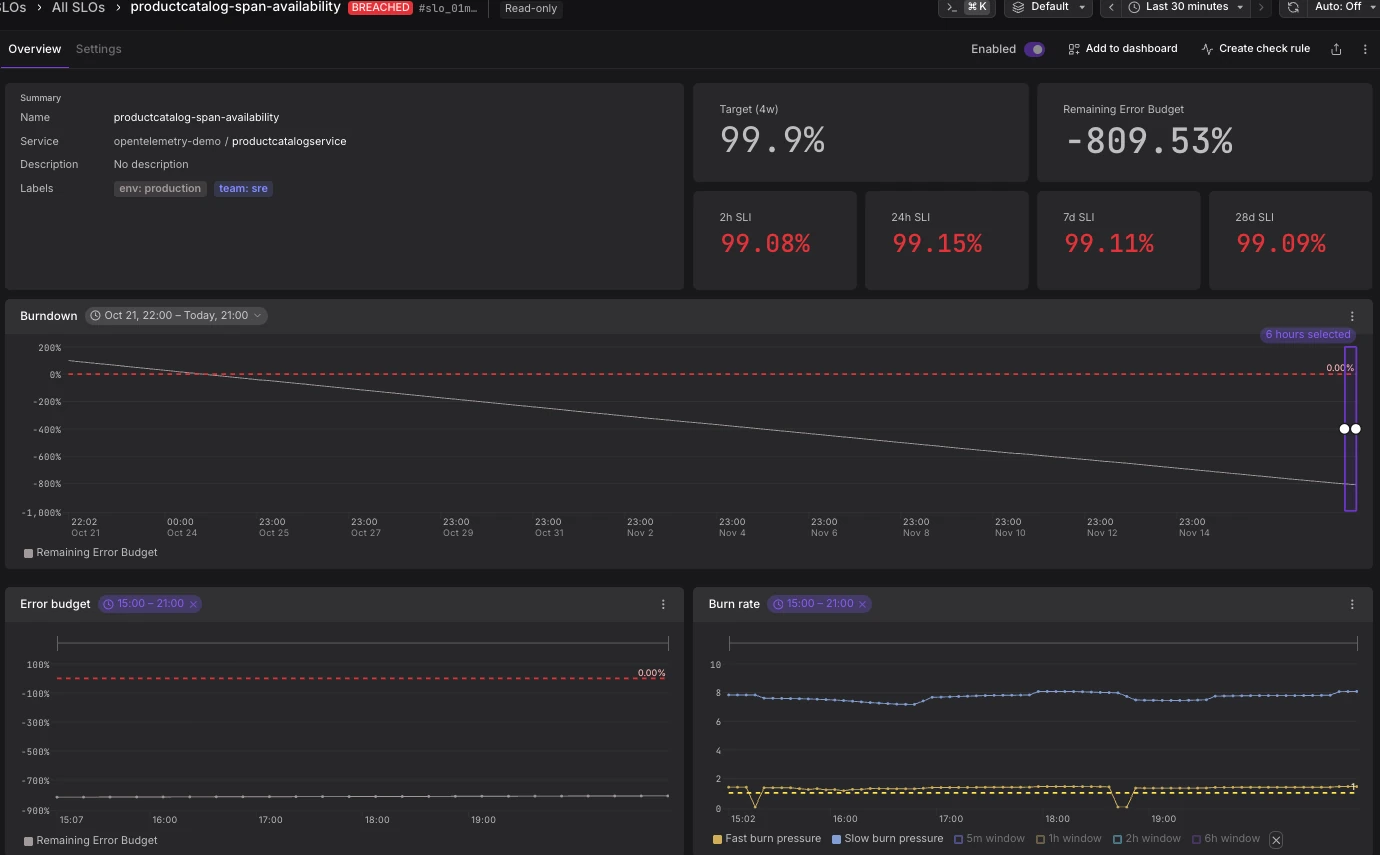
An SLO tracks how fast your error budget is being consumed over a rolling time window (currently 28 days) and exposes burn-rate metrics (dash0.slo.burn_rate.fast, dash0.slo.burn_rate.slow). Alerting on an SLO is done with a check rule on those metrics, so you alert on burn rate rather than on each individual violation. This provides a more strategic view of reliability compared to threshold-based check rules. See Alert on SLOs.
The SLO overview shows its target, remaining error budget, SLI history, and burn-rate signals. A breached SLO can have a negative remaining budget:
Further Reading
Check Rules
- Create Check Rules — Set up check rules to monitor metrics, logs, spans, and web events using PromQL expressions and threshold values.
- Investigate Failed Checks — Troubleshoot failed checks by exploring the underlying telemetry and identifying root causes.
- Send Check Rule Notifications — Configure notification channels to keep your team informed when checks fail.
- Route Check Rule Notifications — Use label-based routing to direct alerts to the right teams automatically.
SLOs
- About SLOs — What SLOs are, how they track an error budget with burn rate signals, and key concepts for measuring reliability.
- Create SLOs — Create and manage SLOs in the UI, with Agent0 or manually, or as code with Terraform or the Dash0 CLI using OpenSLO definitions.
- View and Analyze SLOs — Use the SLOs catalog and SLO detail page to assess reliability with error budgets and burn-rate views.
- Alert on SLOs — Build burn-rate check rules on the SLO metrics and cover the no-data case.