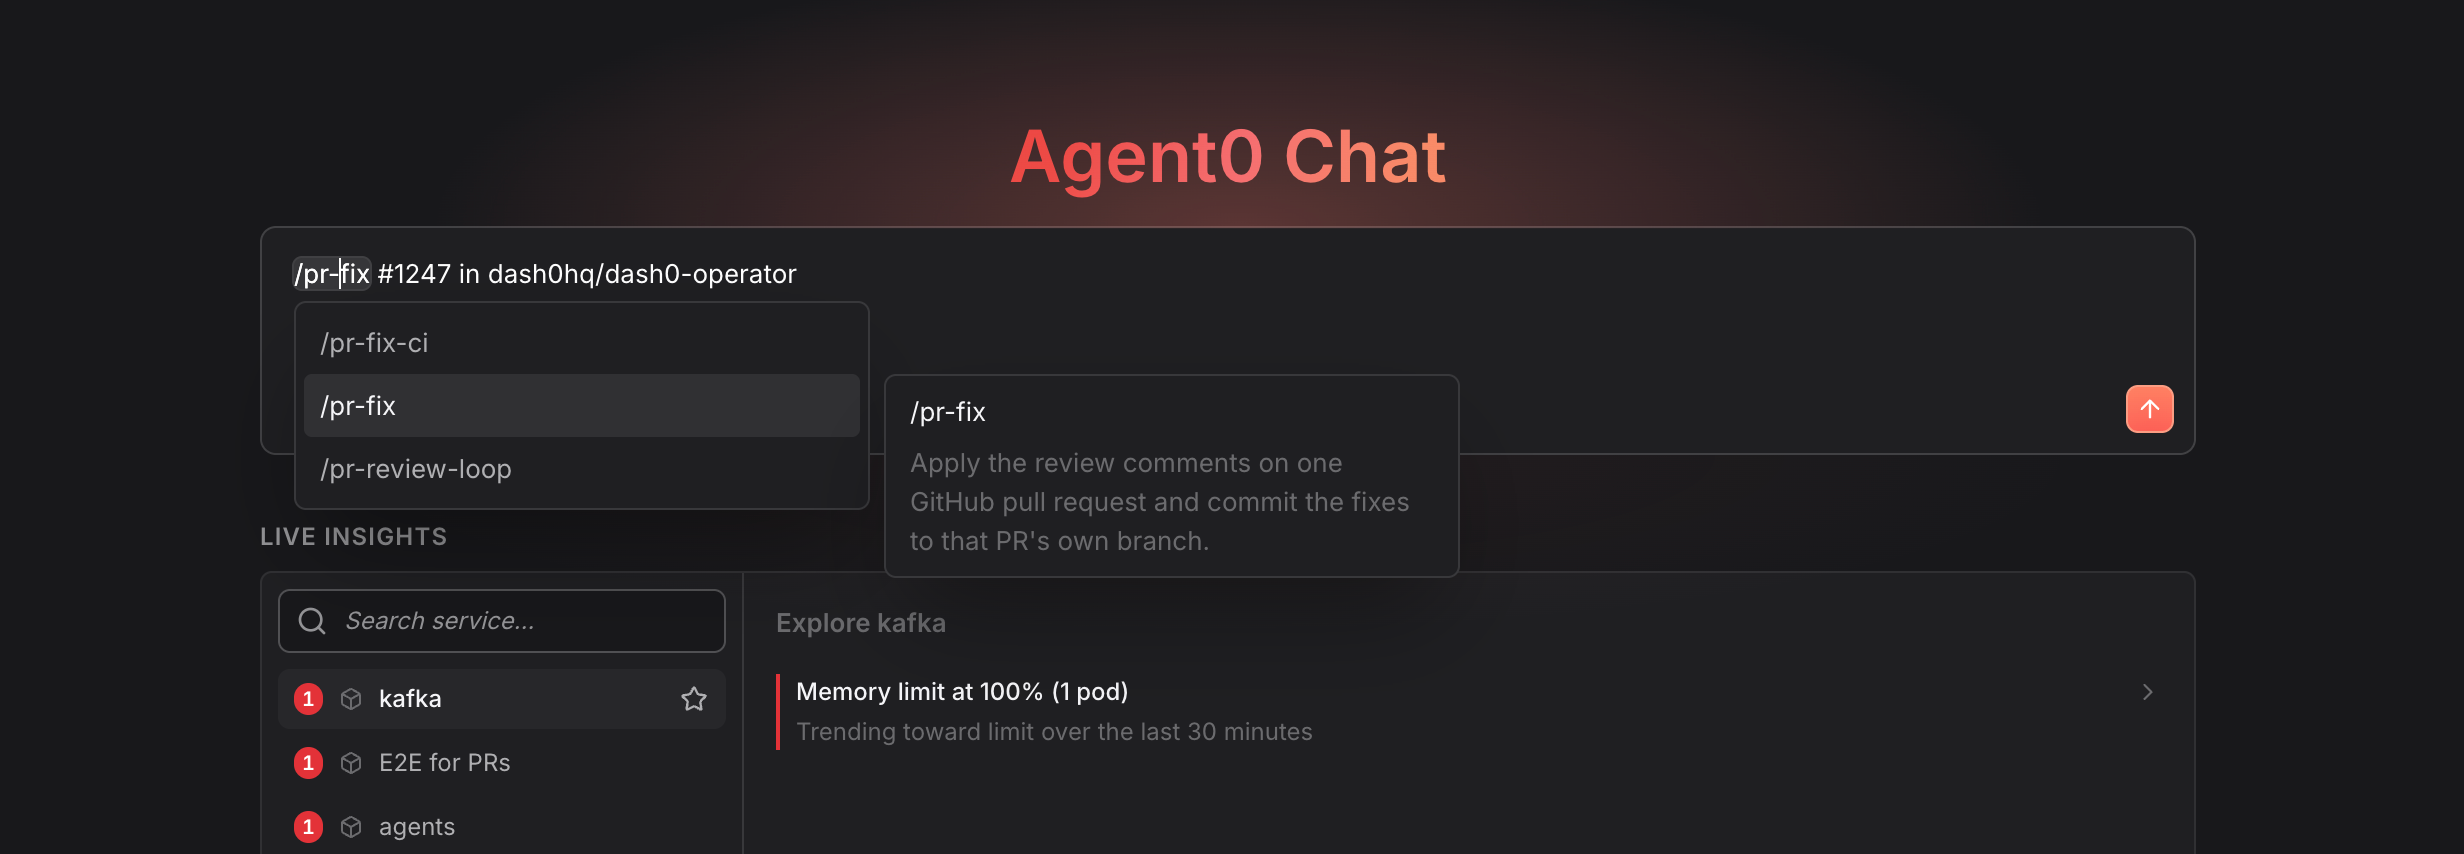
Admins can now import Agent0 custom skills from GitHub and GitLab, pick the ones they want, and pull in changes with one click.
If your team keeps runbooks and agent skills in Git, next to the code they describe, Agent0 couldn't use them directly. Until now, bringing them to Agent0 meant copying each one into Dash0 by hand, and the copies drifted as soon as someone changed the original.
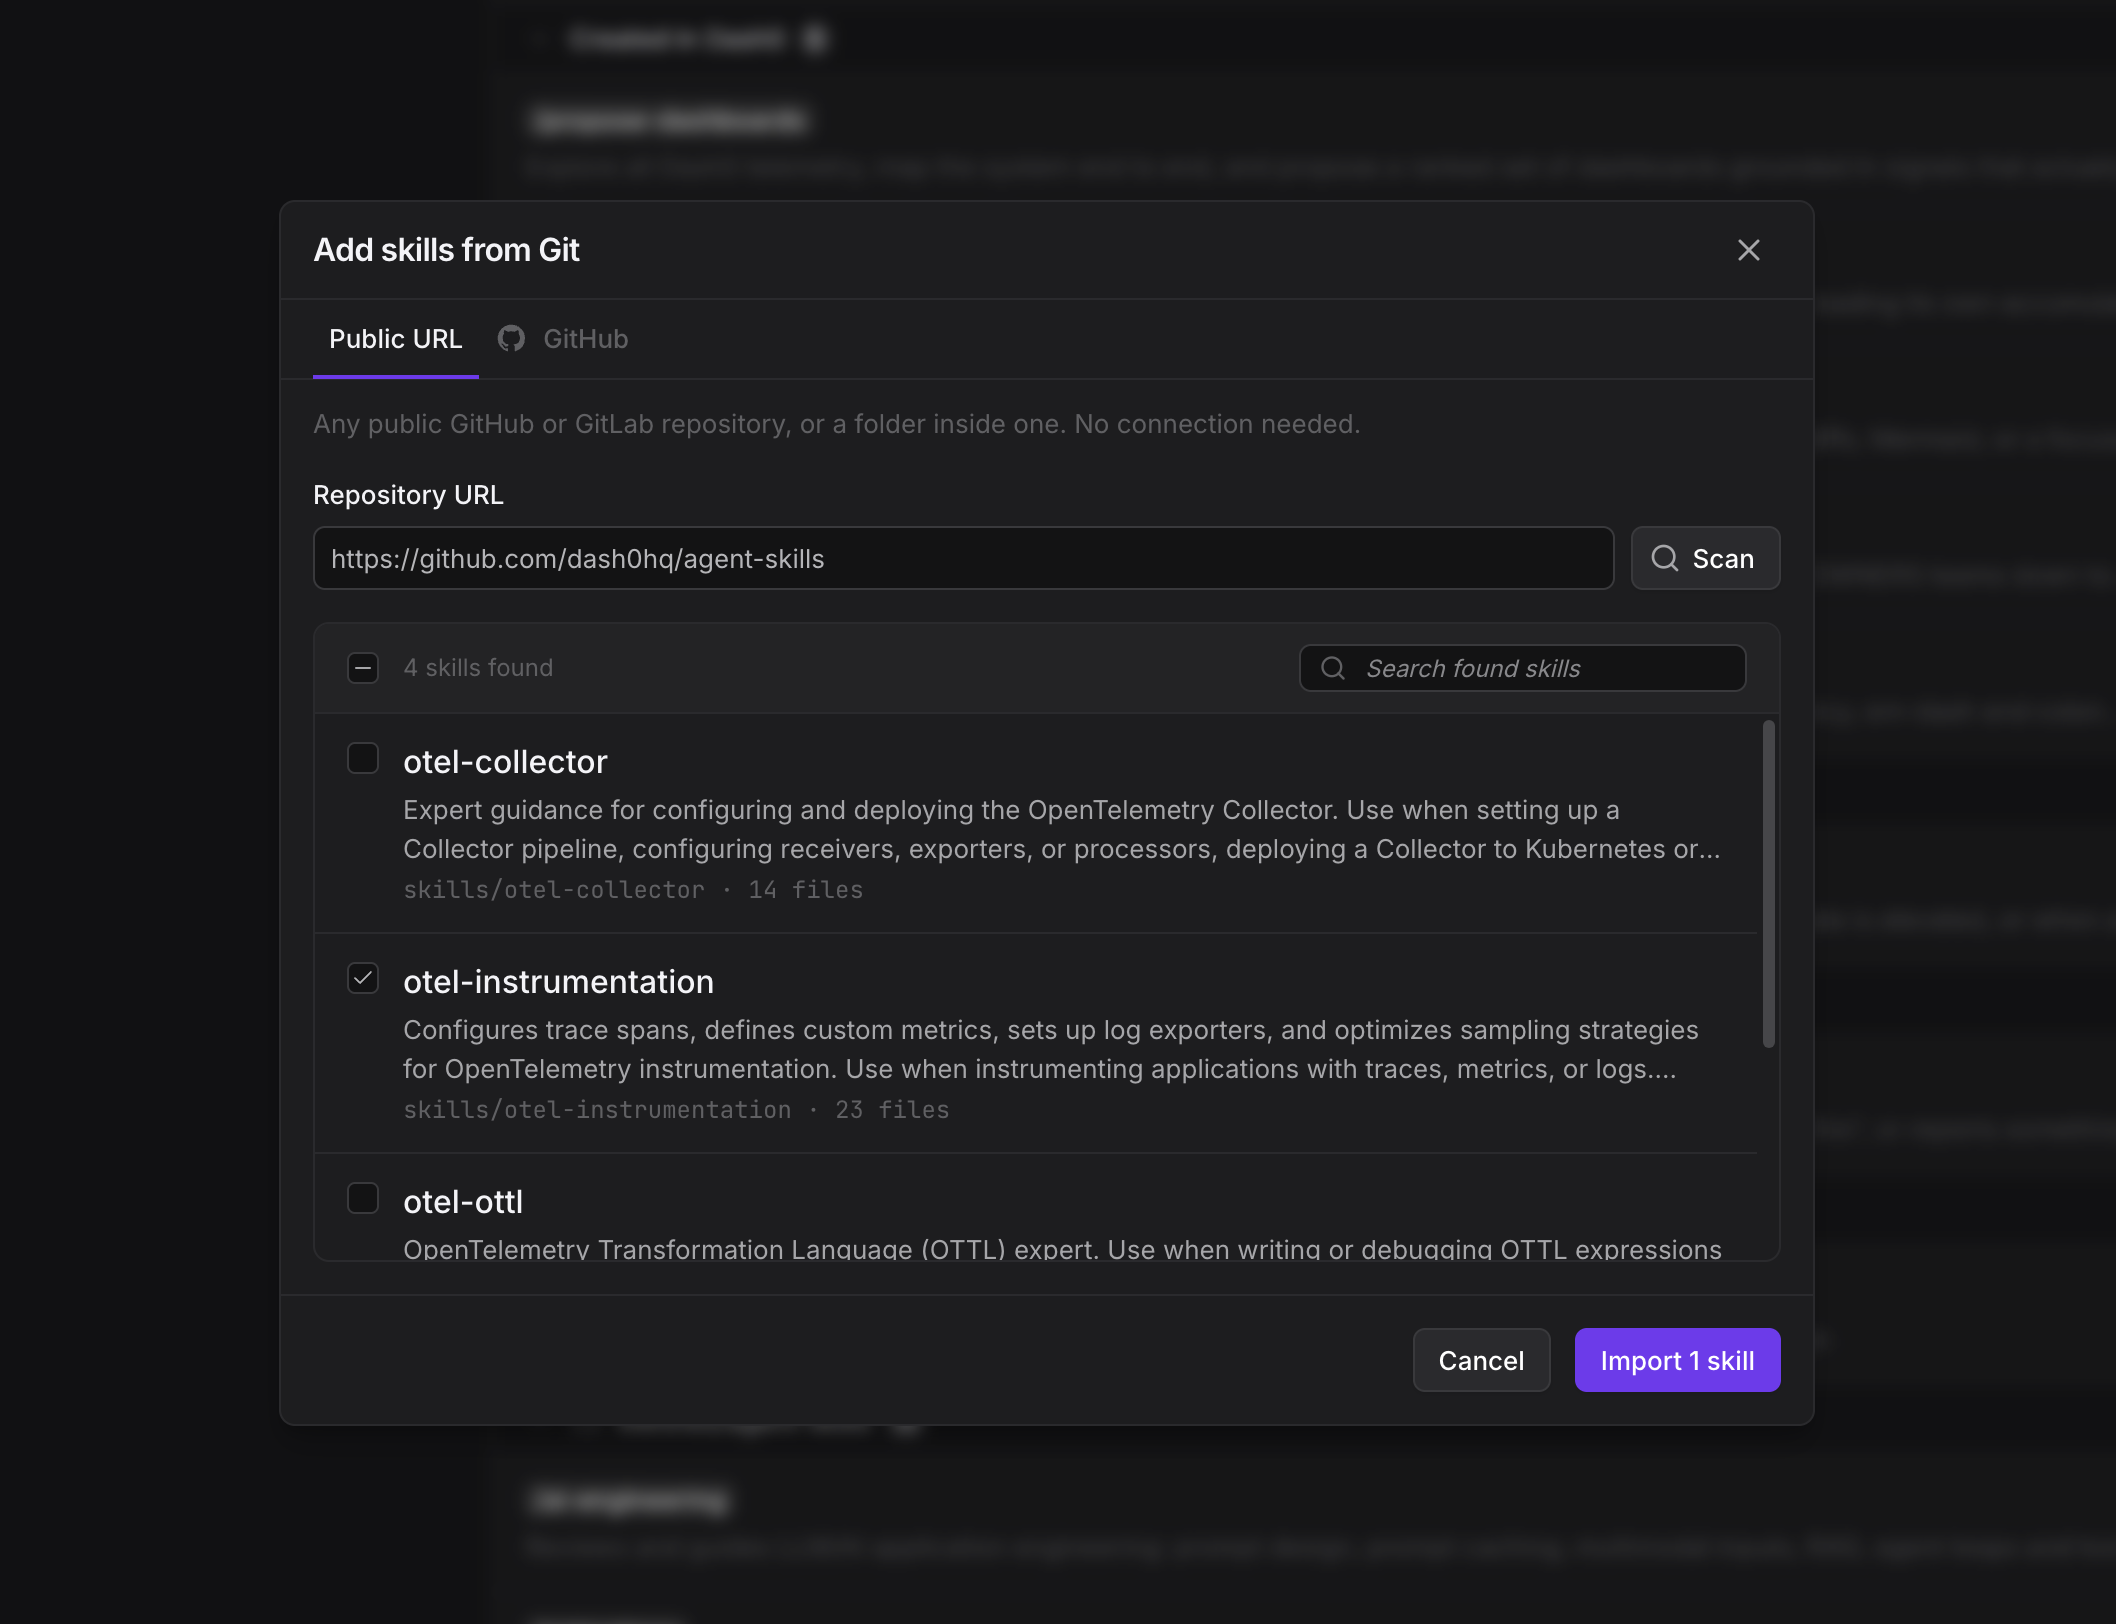
Now an admin can import them. In Organization Settings > Agent0 > Skills, select Import from Git. Scan any public GitHub or GitLab repository, or a private GitHub repository through the GitHub integration. Dash0 finds every SKILL.md, including skills with supporting files, and imports the ones you select. When a skill changes in the repository, select Update and Dash0 reads it again from the branch or tag you imported from.
A new dataset setting masks payment card numbers and replaces verification codes, PIN blocks, and track data in logs, spans, web events, and metrics before Dash0 stores them.
Telemetry from payment paths can carry cardholder data, such as a card number in a logged request body, a query string, or an exception message. Filtering it at the source is the strongest control, but a new service or a forgotten rule can still let one through.
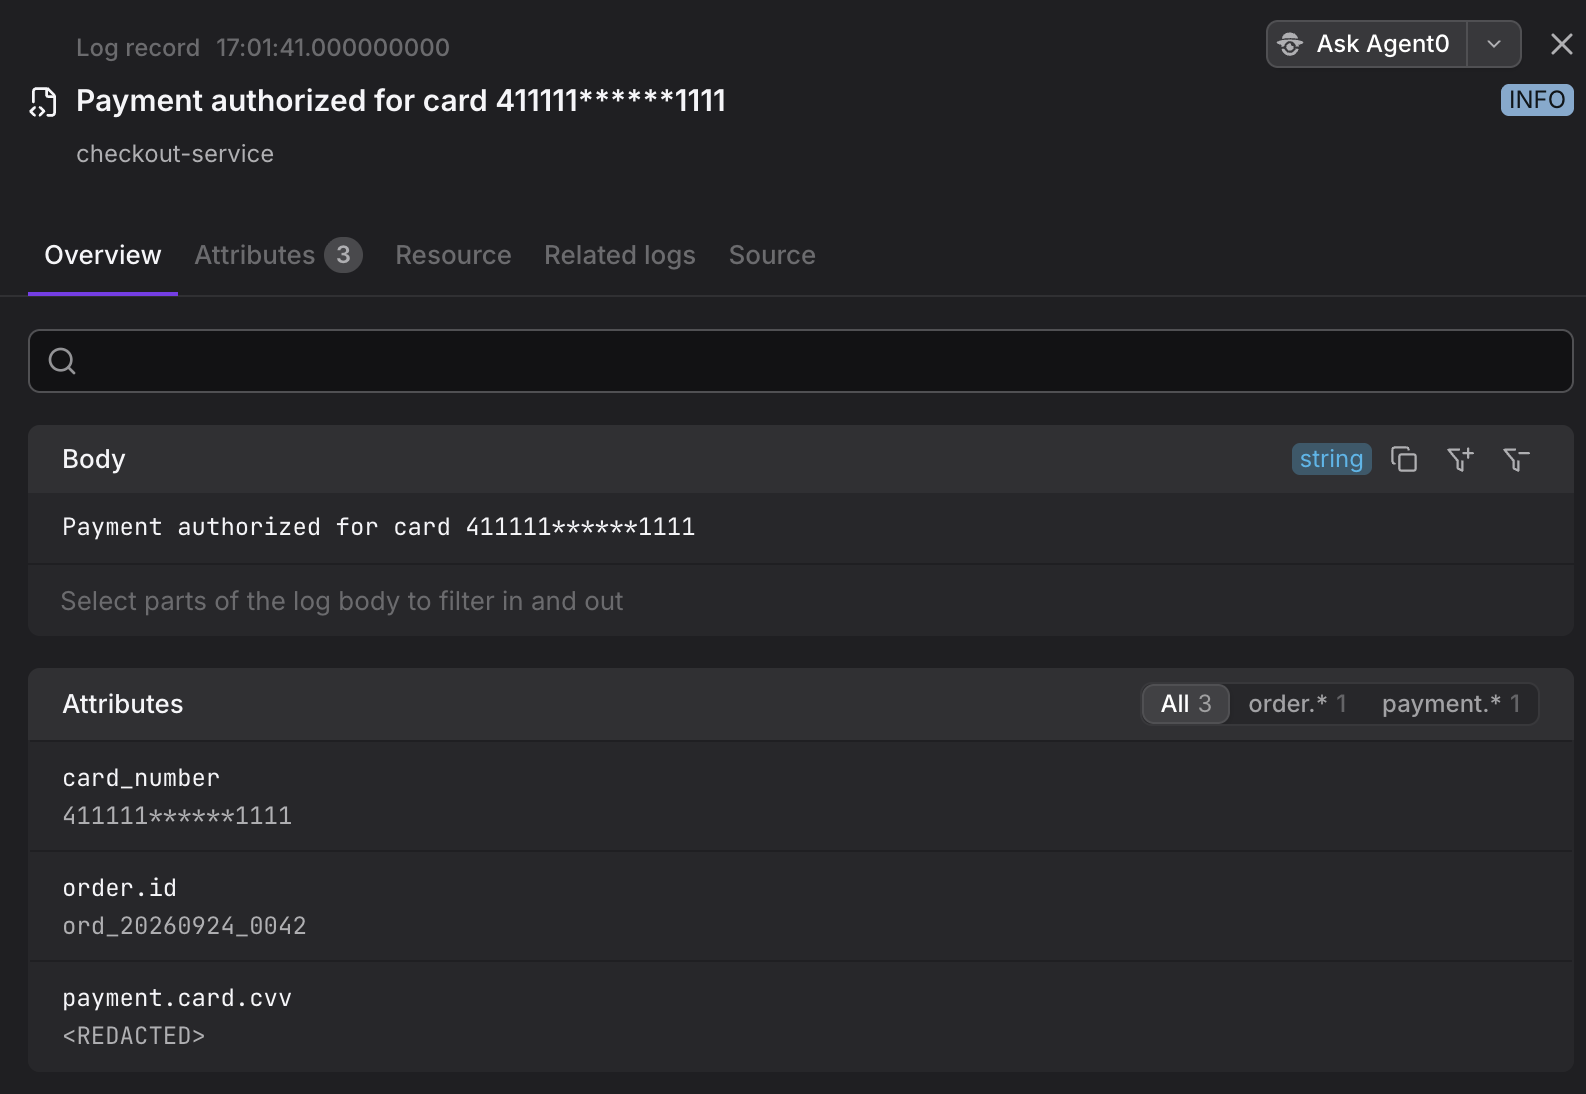
Turn on Redact cardholder data for a dataset, and Dash0 detects likely card numbers in logs, spans, web events, and metrics before it stores them. Card numbers keep their first six and last four digits, such as 411111******1111. Verification codes, PIN blocks, and track data become <REDACTED>. Dash0 never drops a record, so traces and log searches keep working. Detection is pattern-based, so it does not catch encoded, encrypted, or split card numbers.
Two metrics, dash0.redaction.values_scanned and dash0.redaction.values_redacted, show what Dash0 scanned and what it redacted. See Redact Cardholder Data for what gets redacted, the limitations, and how to turn it on.
A new Forecast tab projects your spend for a full billing cycle, priced against your real tiers, right on the Billing & Plans page.
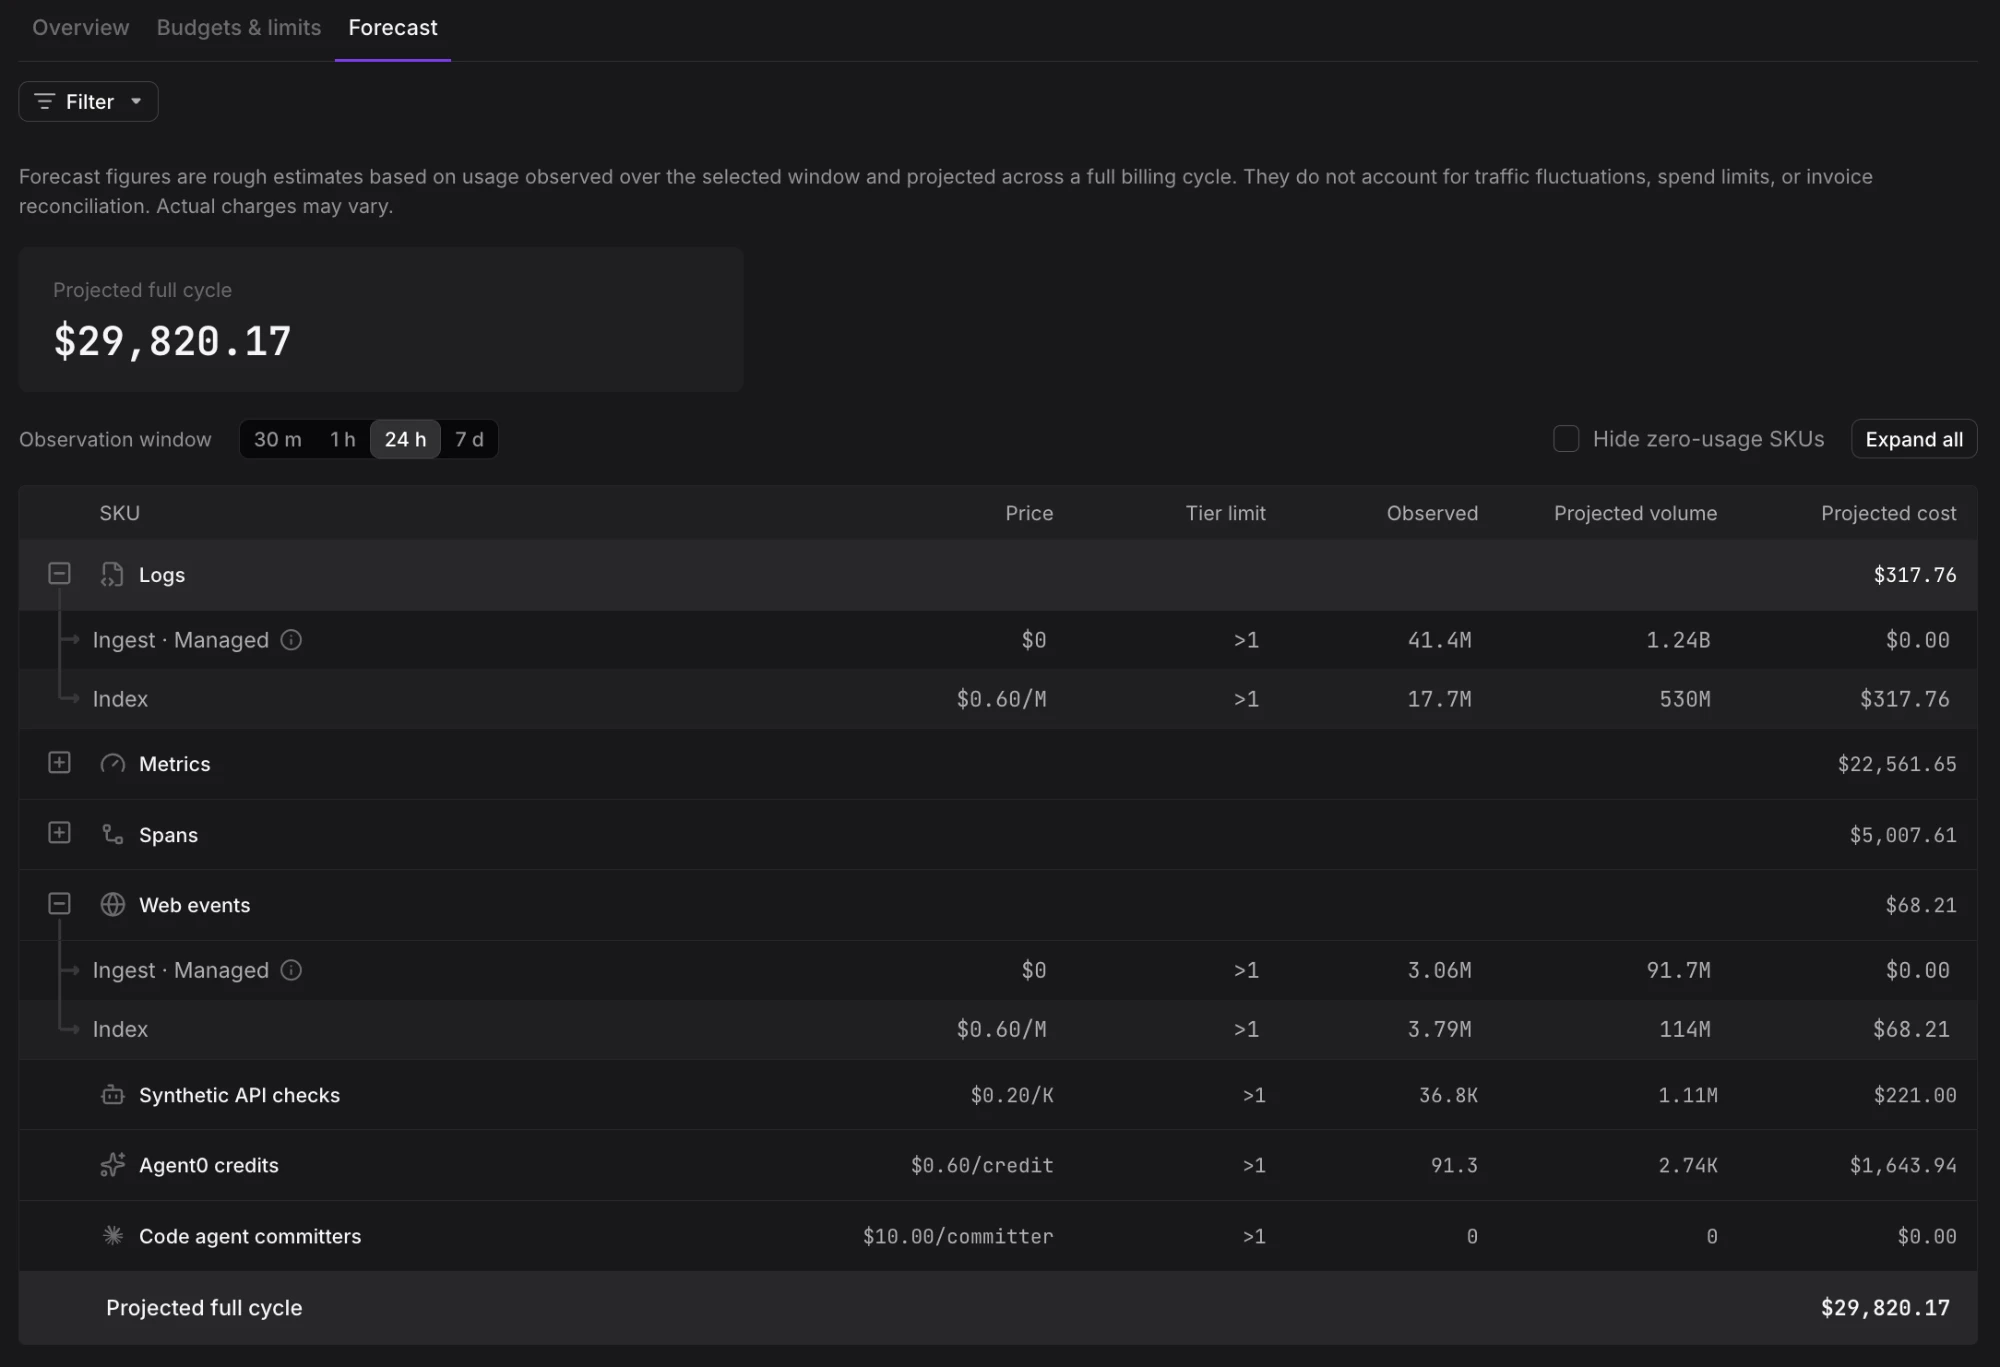
The new Forecast tab projects what you'll spend for a full billing cycle, based on your recent usage rate. Pick a baseline window and Dash0 scales that window's usage rate to a full cycle, then prices it against your org's real pricing tiers and any custom prices, the same way your invoice is calculated, broken down by SKU and dataset.
This is now the recommended way to estimate spend. See Forecast Your Spend to get started.
Automations now trigger on GitHub Actions workflow runs, jobs, manual dispatches, check runs and check suites, filtered by conclusion, status, branch or workflow name.
A failed CI run is usually the first sign that something is broken, but acting on it still takes a person.
Someone has to notice the red build, open the logs, and work out what changed before anything gets fixed.
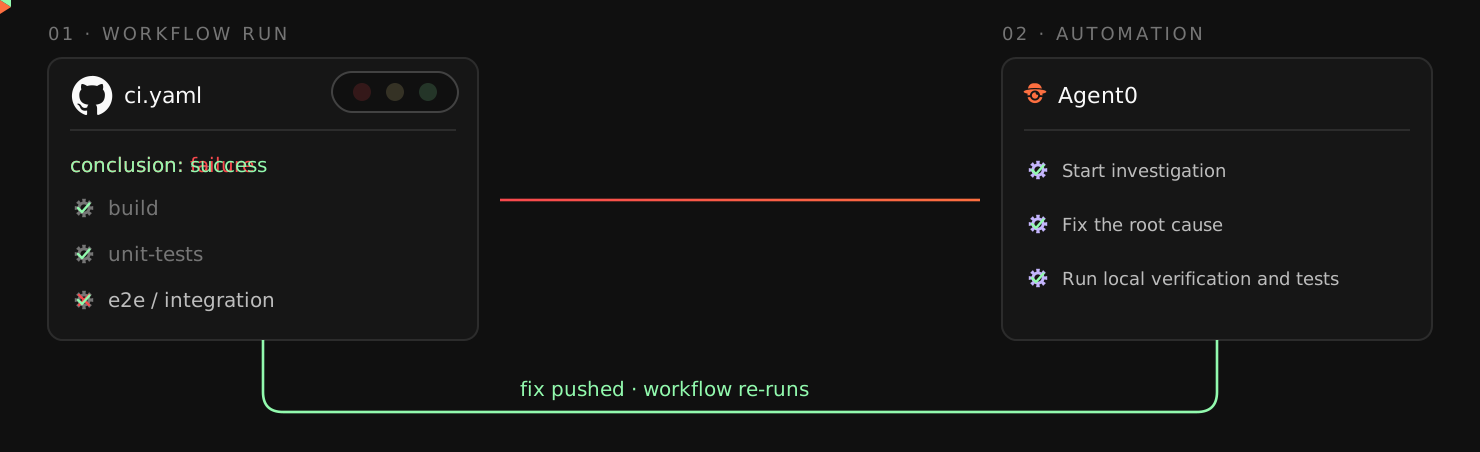
Automations now trigger on five GitHub Actions events: workflow runs, workflow jobs, manual workflow dispatches, check runs and check suites.
Scope any of them by organization, repository, branch or workflow name, and filter by conclusion or status, so an automation starts on the failures you care about and stays quiet for everything else.
From there the automation picks up the failed run, works out why it broke, and can push a fix so the workflow runs again.
See the documentation to set one up.
Uptime tells you your servers are fine. Service level objectives tell you your customers are, on any signal you already send to Dash0.
Most teams know, deep down, that they should have service level objectives. Far fewer actually do, because getting there is a whole project. You have to agree on what to measure, write the queries behind it, tune the thresholds, and hope you picked the right ones.
Dash0 now paves for you the road to SLOs. Find SLOs under Alerting, point one at any signal you already send, and you get two numbers: how much failure you can still afford this month, and how fast you are using it up. Agent0 drafts the definition if you are not sure what to measure. One click turns the SLO into an alert, so you find out before the month is gone.
Define your SLOs in Dash0, or keep them in your repository and apply them with the CLI or Terraform (and soon the Operator for Kubernetes). True to our commitment to open standards, we use OpenSLO as the serialization format, the same way we use OpenTelemetry for telemetry, Perses for dashboards, and PromQL for queries. This enables you to define your service levels with zero vendor lock-in.
Install the operator in OpenShift via Helm and start sending your telemetry to Dash0.
Starting with version 0.155.0, the Dash0 Operator is compatible with OpenShift and can be installed via Helm as usual.
To do this, set operator.openShift.enabled to true. The operator will then deploy the required SecurityContextConstraints resource, allowing its components to run with the privileges they need to function correctly.
The new sync-assets action keeps your dashboards and check rules in sync with your repo, right from CI.
When you're doing GitOps and you're deleting a dashboard, check rule, or any other asset from your repo, it should disappear from Dash0, too.
Wiring that kind of cleanup into a GitHub Actions workflow took a significant effort, since the right way to do it changes depending on what triggered the CI run.
The new sync-assets action handles that for you.
Add it to a workflow (see the documentation), and it keeps assets in sync on every push, manual run, and scheduled run, with no additional tooling or state management needed.
Anyone with read access to a dataset can now create, edit, and delete Agent0 automations in it, the same way they already can with dashboards. Setting up an automation no longer needs an administrator.
Agent0 automations now follow the same permission model as dashboards. Anyone with read access to a dataset can create automations in it, and can edit and delete the automations created there, including ones somebody else made.
Automations managed as code through the API or Terraform stay read-only in Dash0. Update those at their source and apply again. Everyone can still read them, and administrators can delete them. To narrow or extend access on a single automation, use the Permissions section of its general settings.
Agent0 now runs on the model you choose. Pick a level per thread, per automation, or as your default for Chat, Automations, Slack, and MCP, and trade credits for capability where it matters.
Not every question deserves the same model. Reading one service's error logs is cheap work. Chasing a symptom across four services during an incident is not, and answering it with a model that cannot hold the whole picture wastes more than credits. Until now Agent0 made that call for you, on every run, with no way to change it.
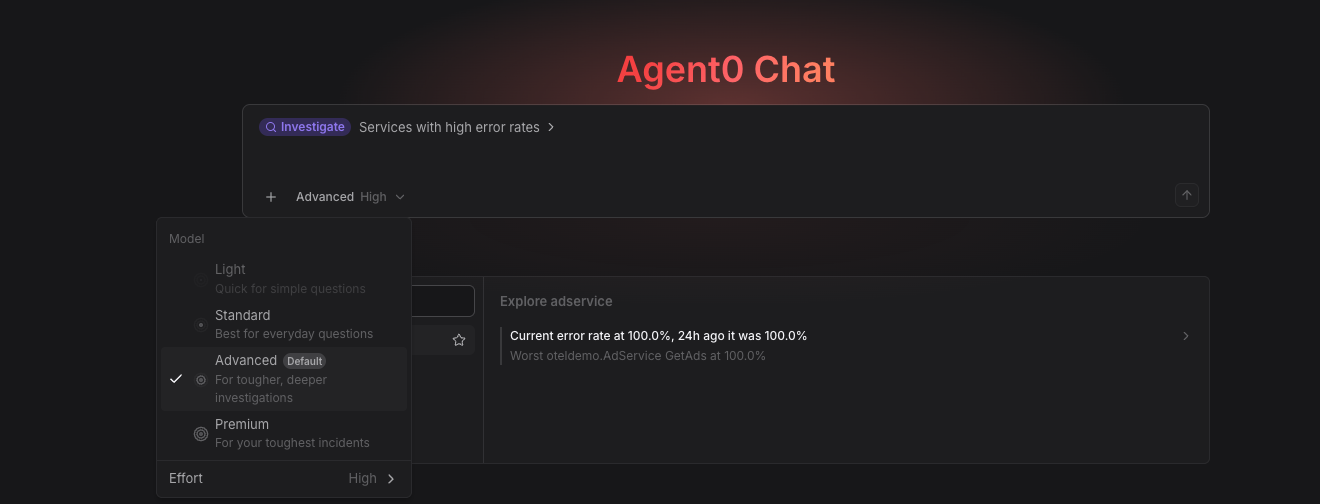
Agent0 now offers four levels, Light, Standard, Advanced, and Premium, plus a reasoning effort that controls how long the model thinks before it answers. Pick one in the Chat prompt toolbar, store one on an automation, name one on an MCP runTask call, or set your own default for each of those under Settings → Agent0. Slack answers say which level and effort they ran with and link to the Slack default in settings. A level names a capability step rather than a model, so Dash0 keeps the model behind each one current and your setting keeps meaning what you chose. Credits are charged on what a turn consumed, priced at the model that served it, so the cost of a level is the cost of the run and not a flat surcharge. Each answer reports the level and effort it ran with. See Model Selection.
One thing to know before your next invoice. Agent0's default level is now Advanced, up from the single model every run used before. It answers harder questions on the first pass, and it uses more credits per turn than the old default did. If your work is mostly routine triage, set your Agent0 Chat and Automations defaults to Light or Standard under Settings → Agent0 and keep the old cost profile. Every run shows its real credit cost, and a monthly credit budget still caps the total.
Not every level runs in every region. A level Dash0 cannot serve for your organization is disabled in the picker with the reason.
AI Coding Insights becomes AI SDLC Insights. One page shows what your coding agents cost, who has adopted them, which tools and skills they lean on, and how AI-assisted pull requests move from first prompt to merge.
Most engineering organizations can say what they spend on coding agents. Fewer can say what that spend buys. Do AI-assisted pull requests merge faster than the rest, or do they pile up waiting for review? Which teams and repositories have picked the agents up, and which tools, MCP servers, and skills do those agents lean on? The answers sit between agent telemetry and your pull requests, and they are hard to read together.
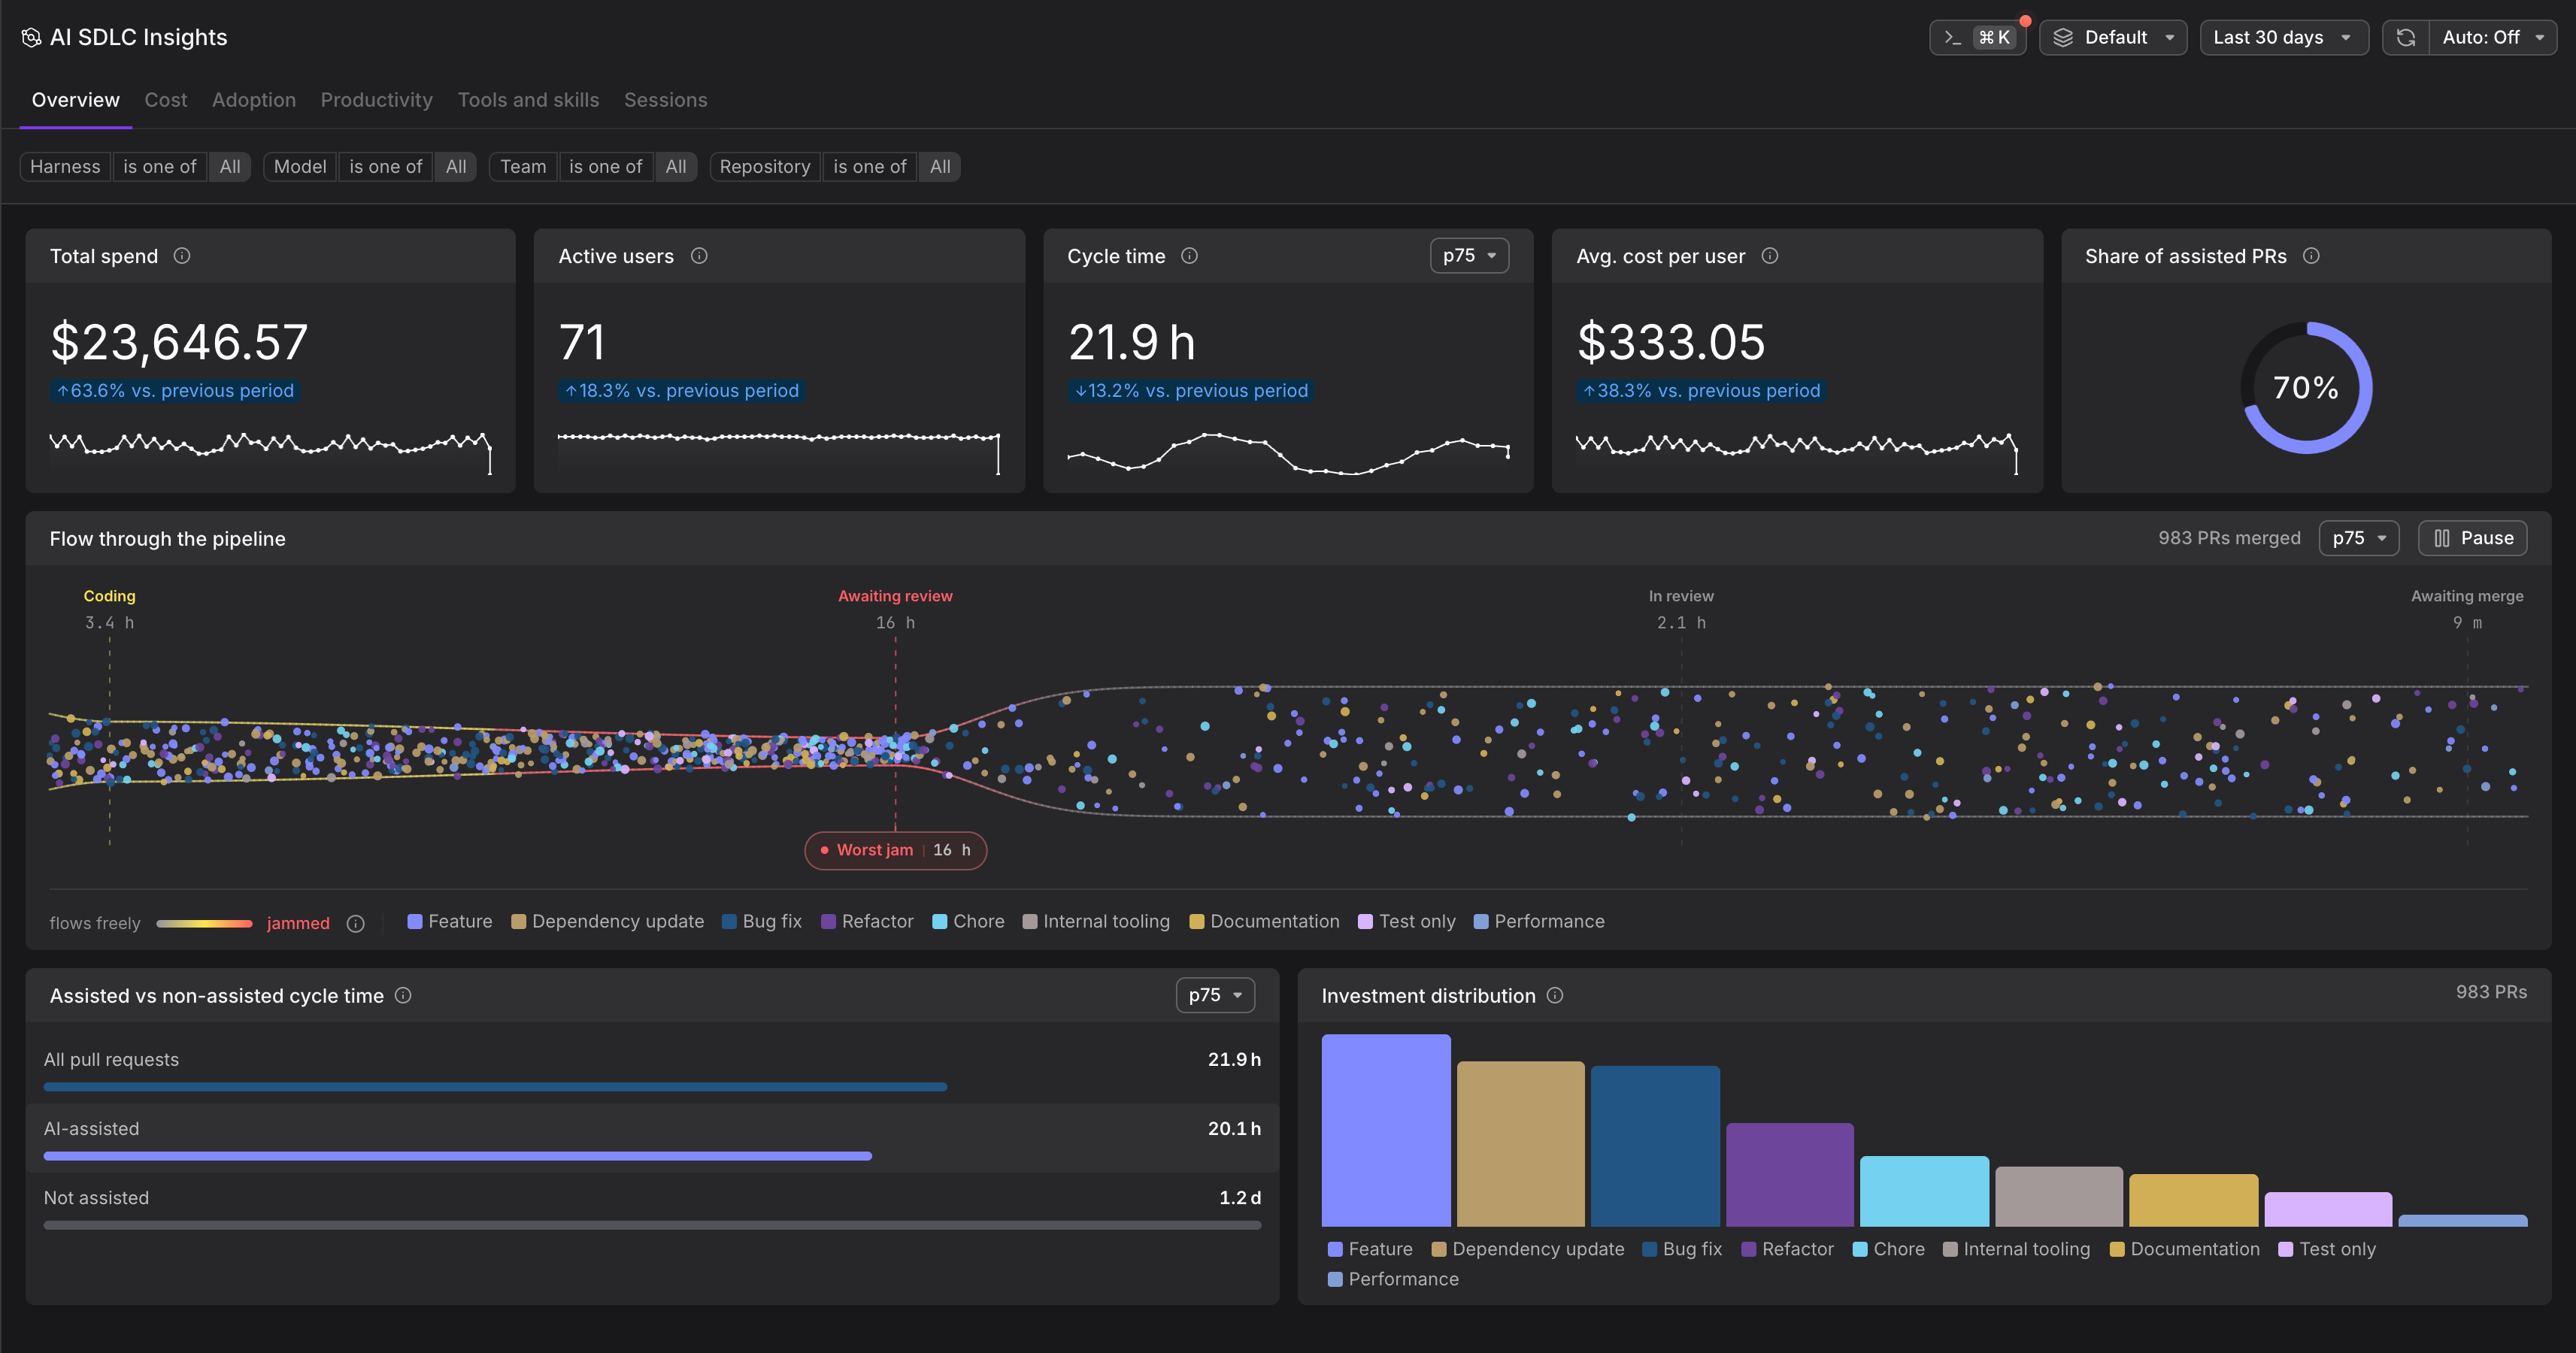
AI SDLC Insights is the reworked successor to AI Coding Insights, and it reads them together. The Overview leads with total spend, active users, cycle time, average cost per user, and the share of assisted pull requests. Flow through the pipeline shows where merged pull requests slow down between coding, review, and merge, and Assisted vs non-assisted cycle time compares the two at the percentile you choose. Cost, Adoption, Productivity, and Tools and skills each go deeper, with pull request metrics such as time to first review, pull requests awaiting first review, and review depth per merge. Every entry in Sessions opens a details page with its prompts, tools, and conversation. Links into AI Coding Insights redirect to the new page.
HTTP semantic-convention attributes on Lambda handler spans used to depend on your runtime — now the extension extracts them itself, for every language.
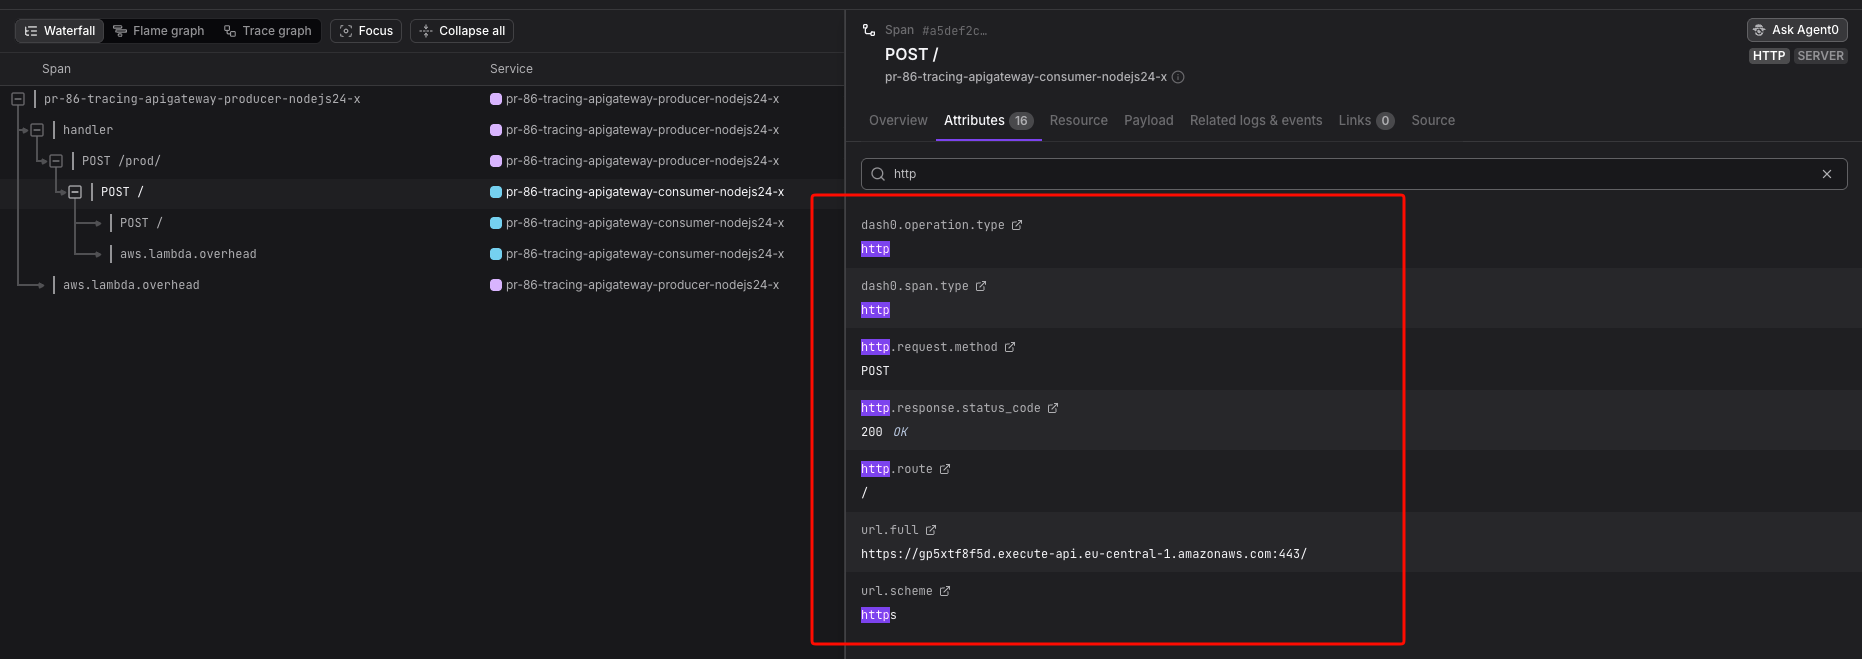
HTTP semantic-convention attributes on a Lambda handler span — http.request.method, http.route, http.response.status_code — used to depend on which language you deployed in. Python's auto-instrumentation extracted them from the API Gateway event; Node.js got nothing.
The Dash0 extension now does this parsing itself, independent of any runtime SDK. It reads the raw Lambda invocation and response payloads directly, so it works the same way for every supported runtime. If no runtime SDK is loaded to create the handler span, the extension creates that span itself and sets the attributes on it.
Covered triggers: REST API (v1) and HTTP API (v2) proxy integrations, and Lambda Function URLs. Each handler span gets http.request.method, url.path, url.scheme, http.route, server.address, server.port, client.address, network.protocol.version, and http.response.status_code attached automatically — no code changes required.
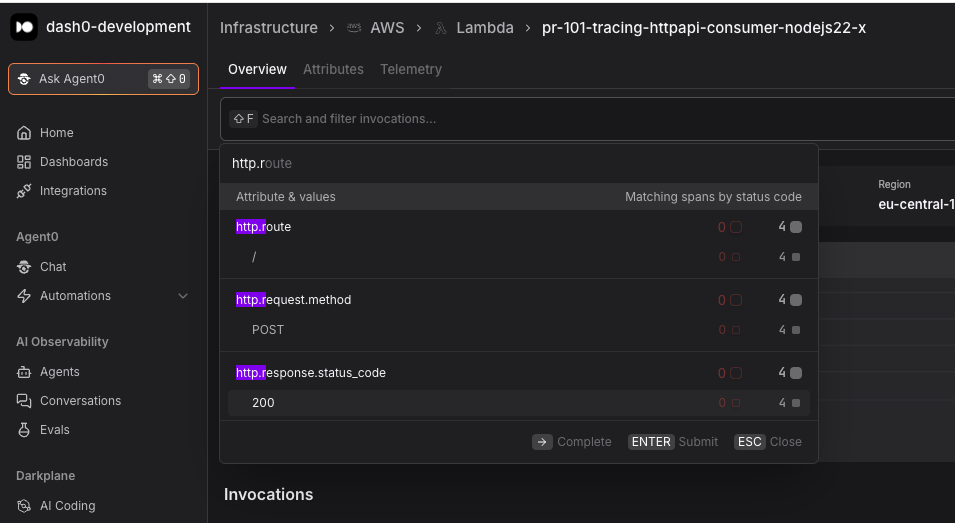
Because these are ordinary span attributes, you can filter and group on them right away, both in the Trace Explorer and in the invocations view of a Lambda function. Filter by http.response.status_code to pull up only the failed invocations, or group by http.route to see which endpoint is responsible for them. This makes triage faster: a noisy function narrows down to one endpoint and one status code without you touching any code.
In order to use this new feature, upgrade to the dash0 lambda extension version 23 or higher.
Teach Agent0 the procedures only your team knows. An admin can now write custom skills for your organization, and anyone can call one in a chat with /, or let Agent0 pick the right skill on its own.
Agent0 already knows how to query spans, build a PromQL query, or create a dashboard. What it could not know is how your team works: the runbook you follow when checkout latency climbs, how your environments and datasets are named, what to check first for a problem you have seen before. Until now that context lived in your head, and you retyped it every time.
Now an admin can write it down once. In Organization Settings > Agent0 > Skills, add a custom skill with a name, a description of when Agent0 should use it, and the instructions to follow. Everyone in your organization can then invoke it by typing / in a chat, and Agent0 also reaches for a skill on its own when its description matches the request.